Atlassian Jira Service Desk: A 2026 Setup Guide for Teams
Struggling to configure atlassian jira service desk? Learn a 2026 setup approach to streamline requests, routing, and reporting. Read now.
Setting up Atlassian Jira Service Desk can feel deceptively simple. You create a project, add a few request types, and expect support work to flow smoothly.
Then reality arrives. Customers choose the wrong forms, urgent tickets sit beside routine questions, agents miss ownership changes, and managers struggle to explain where time goes. Small configuration choices can create daily friction across your service team.
But here's the truth: Jira Service Desk, now called Jira Service Management, works best when you design the service experience before adding detailed settings. This guide walks you through a practical 2026 setup, including request forms, queues, workflows, automation, permissions, reporting, and rollout checks.
How to Set Up Atlassian Jira Service Desk in 2026
Atlassian Jira Service Desk is now Jira Service Management, a service platform for collecting requests, routing work, managing incidents, and tracking service performance. Existing teams may still use the older name because earlier Jira Service Desk projects continue to appear in historical conversations and search results.
For a reliable setup, begin with the service you want to deliver. Then configure the project around request categories, responsibility, urgency, communication, and measurable outcomes.
- Define the service scope. Write down which team owns the service, who can request help, what types of work belong in the portal, and which requests need another channel.
- Create the service project. Choose a project template that matches your work, such as IT support, HR help, facilities, or general business service. Give the project a clear name that makes sense to the people requesting help.
- Plan request types. Group common needs into plain-language choices. “Laptop access,” “new employee setup,” and “software problem” are easier to understand than internal workflow labels.
- Build request forms. Ask only for information needed at the start. Add conditional fields when a response should reveal a follow-up question, such as an affected system or business impact.
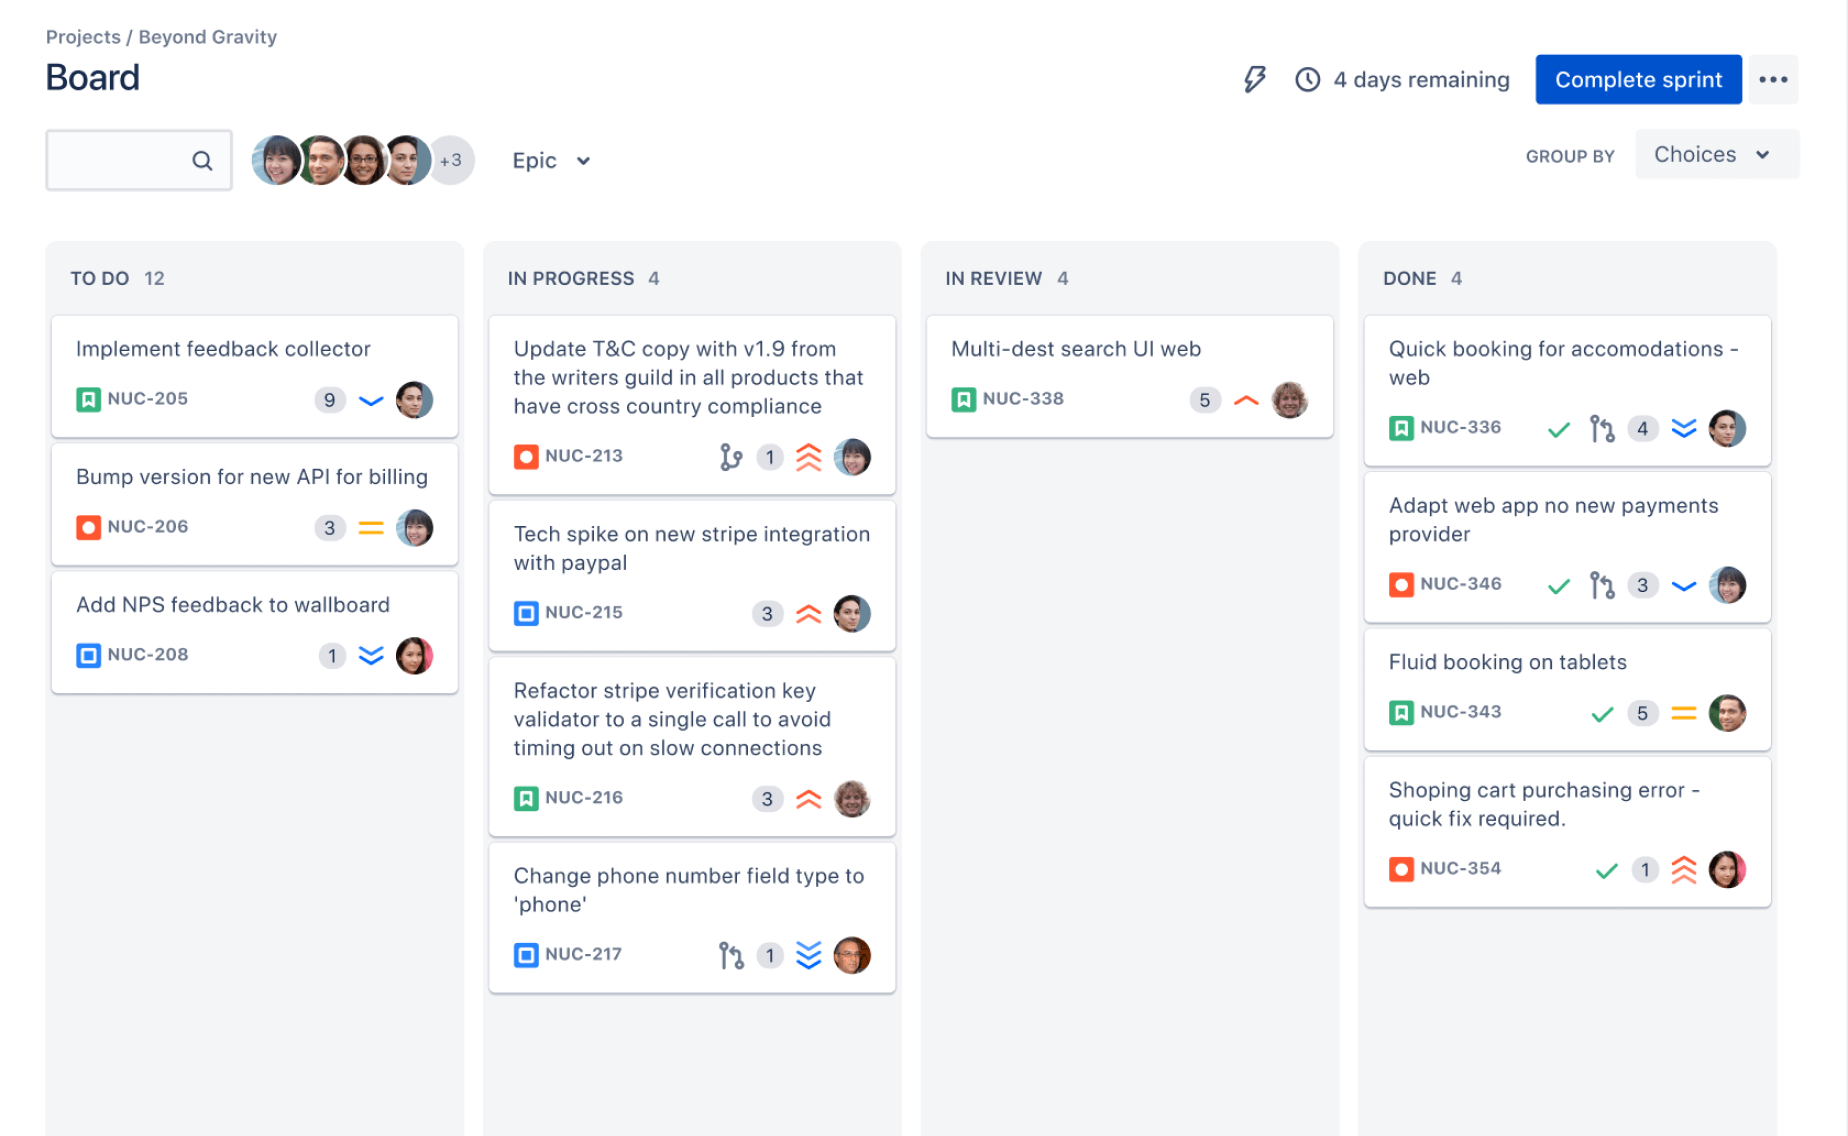
- Configure workflows and statuses. Map the journey from arrival to completion. A small team might use Open, In Progress, Waiting for Requester, Resolved, and Closed.
- Set up queues and ownership. Create views for unassigned work, urgent requests, overdue items, waiting responses, and work assigned to each team. Make the next action obvious.
- Add service targets and automation. Define response and resolution targets by priority or request type. Use automation for routine actions, such as assigning a category, notifying a manager, or closing an inactive request.
- Configure access and notifications. Decide who can raise requests, view requests, approve work, administer the project, and receive alerts. Keep notifications useful by avoiding messages for every minor field change.
- Connect helpful integrations. Add email, chat, asset information, monitoring alerts, or identity tools when they reduce manual handling. Test each connection with realistic scenarios.
- Test the complete journey. Submit requests as a requester, process them as an agent, approve them as a manager, and review the resulting metrics. Fix confusing steps before inviting a larger audience.
Choose a clear service model first
A service project can support many teams, but a single project should still have a coherent purpose. For example, employee technology support and office maintenance may deserve separate portals when their forms, ownership, and targets differ substantially.
Start with a simple service map. List the service area, common request, responsible team, expected response, and completion signal. This prevents configuration from becoming a collection of unrelated settings.
Design request types around real questions
People usually describe a need rather than a technical classification. “I cannot access payroll” gives clearer direction than “authentication incident.” You can preserve technical categories behind the scenes while keeping the portal language familiar.
For example, a new employee request might ask for a start date, department, manager, location, equipment needs, and required applications. That information can trigger several internal tasks without forcing the requester to understand your internal structure.
Create workflows that show progress
Every status should answer a practical question: who owns this work, what is happening now, or what must happen next? If two statuses look identical to an agent, combine them.
A request waiting for customer information should not remain in the same status as active investigation. Separating those states improves queue accuracy and helps you measure delays caused by external responses.
What to Configure Before Launch
The fastest way to create a confusing service portal is to publish it before deciding how work will be categorized. Spend time on the foundations first, because later changes can affect reporting, automation, and historical comparisons.
Request types and portal groups
Use request types that reflect intent. A useful group might include Access, Hardware, Software, Account Help, and General Questions. Each group should contain only the choices people commonly need.
Imagine an employee searching for help with a locked account. If the portal offers “Identity lifecycle event,” the person may choose incorrectly or abandon the request. “Unlock my account” creates a clearer starting point.
Fields and form behavior
Every field adds effort. Keep required fields limited to details that affect routing, priority, approval, or investigation.
Use examples beside difficult questions. Instead of asking for “business impact,” explain that the requester should mention affected people, a blocked deadline, or a critical business activity.
Priorities and urgency rules
Priority should describe business effect rather than emotional tone. A request marked “urgent” may still have low business impact, while a quiet report about a payroll outage may require immediate attention.
| Priority | Practical meaning |
|---|
| Critical | A major service is unavailable, and many people or a vital operation are affected. |
| High | A significant issue limits important work, with a workable alternative possibly available. |
| Medium | A person or small group is affected, but regular work can continue. |
| Low | The request is informational, cosmetic, or suitable for planned handling. |
Roles and permissions
Separate project administration from daily service work. Agents need access to triage and resolve requests, while project administrators manage forms, workflows, automation, and reporting settings.
Review access with a simple test: can each person see only the requests and actions required for their role? This matters when a portal handles employee relations, finance questions, security incidents, or other sensitive matters.
Queues, Automation, and Service Targets
Queues turn a large request list into manageable work. They should help an agent decide what to handle next without opening every ticket individually.
Build queues around decisions
A queue should answer a question such as “What needs immediate attention?” or “Which requests are waiting for our team?” Useful starting queues include:
- Unassigned requests requiring triage.
- Critical and high-priority work.
- Requests approaching a service target.
- Items waiting for requester information.
- Requests assigned to a particular specialist group.
- Recently resolved work awaiting confirmation.
For example, a queue called “All Open Requests” may become too broad as volume increases. A queue called “High impact, no owner” creates a clear action for the person reviewing it.
Use automation for repeatable decisions
Automation is valuable when the same condition produces the same action. A request with “new starter” in its type might receive a standard checklist, an owner, and a target date.
Keep an audit trail for automated changes. When a request moves unexpectedly, the service team should be able to identify the rule, condition, and action that caused it.
Set targets people can understand
Service targets should reflect the promise you can maintain. A two-hour response target may look impressive, yet it creates pressure if the team lacks coverage during evenings or weekends.
Define whether the clock runs continuously or only during working hours. Then explain what “response” and “resolution” mean. A first automated message should not count as meaningful human engagement unless that matches your service policy.
Reporting and Continuous Improvement
Reporting should help you make decisions. A dashboard full of numbers does little if nobody knows what action each metric supports.
Track a useful baseline
Start with request volume, time to first response, time to resolution, breached targets, reopen rates, and satisfaction. Review results by request type, priority, team, and period.
Suppose password access requests make up 35 percent of monthly volume and take little investigation. That pattern may justify better self-service, clearer instructions, or an automated path.
Read trends instead of isolated numbers
A single week can be distorted by a product launch, office move, or major outage. Compare several periods and look for recurring changes.
A falling resolution time with rising reopen rates may indicate that agents are closing requests too quickly. A high satisfaction score with a growing backlog may show that easy requests are receiving attention while complex work waits.
Turn recurring requests into improvements
Review the top request categories each month. Ask whether the problem comes from unclear guidance, a broken process, missing access, or a product defect.
For example, repeated “How do I request access?” tickets may signal that the portal needs a clearer access path. The improvement is successful when people can complete the request with fewer questions and less agent intervention.
Launching the Service Portal Without Disruption
A strong launch is a change-management exercise as much as a configuration exercise. People need to know where to go, what information to provide, and what response to expect.
Run a pilot with realistic scenarios
Choose a small group that represents different roles and technical comfort levels. Ask them to submit ordinary requests, urgent issues, approval requests, and incomplete submissions.
Watch where they hesitate. If several testers select the wrong request type, revise the wording before launch. If agents create manual notes to compensate for missing fields, improve the form.
Prepare a short launch message
Tell people when the portal opens, which requests belong there, how urgent incidents should be reported, and how to check progress. Include one or two examples rather than a long explanation.
For instance, “Use the portal for access, equipment, and software help. Call the incident line if a critical service is unavailable” gives clearer direction than a general announcement.
Review the first month carefully
During the first few weeks, review abandoned requests, reassigned work, breached targets, duplicate submissions, and questions sent through other channels.
These signals reveal where the service design conflicts with real behavior. Adjust the smallest useful part first, then measure whether the change improves the journey.
ONES.com Solution for Service and Project Work
Value Proposition
ONES.com combines project management and knowledge management in one platform, with AI support through ONES Assistant. ONES Project can support service and delivery workflows as a Jira alternative, while ONES Wiki provides a connected knowledge environment as a Confluence alternative.
Teams can buy ONES Project and ONES Wiki separately. The platform supports Cloud, On-Premise, Private Cloud, and Air-gapped deployments, with full feature parity between cloud and self-hosted versions.
Core Capabilities
- Scattered request handling → Jira-compatible workflows → Teams can model familiar stages, ownership rules, and transitions while keeping service work visible in a structured process.
- Manual status updates → Custom workflows and fields → Each service group can capture the details that affect routing, approval, priority, or completion without forcing every team into one rigid design.
- Unclear sprint or improvement work → Sprint management → Recurring service improvements can move into planned iterations, giving teams a practical way to balance support work with larger changes.
- Repetitive triage actions → Automation → Rules can handle routine assignments, notifications, and status changes, reducing manual handling for predictable requests.
- Limited operational visibility → Built-in reporting → Managers can review progress, workload, trends, and delivery performance without assembling separate reporting processes.
- Too many add-ons → Native capability coverage → Core project, workflow, reporting, and knowledge needs can stay closer together, which may reduce dependence on multiple plugins.
- Restricted deployment requirements → On-premise, private cloud, or air-gapped options → Teams with strict network or hosting requirements can select an environment aligned with their operating constraints.
- Disconnected knowledge and delivery work → ONES Wiki alongside ONES Project → Teams can keep guidance, decisions, and project work connected when both products fit the operating model.
Application Scenarios
Internal technology support: An IT team can create request categories for access, equipment, applications, and incidents. Custom fields capture business impact, while workflows separate active investigation from requests waiting for employee details.
Product engineering support: A product team can connect incoming issues to development work, use sprint planning for fixes, and review built-in reports to understand how service demand affects delivery capacity.
Restricted-network operations: An organization with strict infrastructure controls can consider an on-premise, private cloud, or air-gapped deployment while retaining the same core feature coverage available in the cloud version.
Common Challenges and Practical Fixes
Challenge: Too many request types
Why it happens: Every internal distinction becomes a portal choice, leaving people unsure where to begin.
Solution: Combine choices that lead to the same team, target, and first action. Keep technical classifications behind the scenes when they do not help the requester.
Challenge: Agents bypass the workflow
Why it happens: Statuses may be unclear, forms may omit important details, or the process may take longer than a quick message.
Solution: Observe real work and remove unnecessary transitions. Give agents useful queues, clear ownership rules, and forms that capture essential context at the start.
Challenge: Automation creates surprises
Why it happens: Rules overlap, conditions are too broad, or nobody reviews their effect after a configuration change.
Solution: Give each rule a narrow purpose, test it with sample requests, and review its activity regularly. Disable rules that no longer match the service process.
Challenge: Reports do not support decisions
Why it happens: Teams collect many measures without agreeing on what good service looks like.
Solution: Give each dashboard a small set of questions. For example, “Where is work aging?” and “Which request type creates avoidable volume?” lead to more useful reporting than a crowded metric wall.
FAQs
Is Jira Service Desk still available in 2026?
Jira Service Desk was renamed Jira Service Management. The older phrase still appears in searches, older project discussions, and team vocabulary. When you configure a current Atlassian service project, look for Jira Service Management features such as request types, queues, workflows, automation, service targets, and portal settings.
What should I configure first?
Start with service scope, request categories, ownership, priority rules, and the basic workflow. Then build forms, queues, automation, and reports. This order helps you avoid creating fields or rules that do not support a clear service decision.
How many request types should a new portal have?
There is no ideal number for every team. Begin with the choices people make most often, then add a request type only when it changes routing, approval, urgency, or handling. If two choices lead to the same experience, combine them and use internal classification later.
Should every request have the same workflow?
No. A simple question, access request, and major incident may require different stages. Still, avoid creating a separate workflow for every small variation. Use a shared foundation where possible, then add differences only when they affect ownership, approval, communication, or risk.
How can I improve adoption after launch?
Track where people abandon forms, choose the wrong category, email agents directly, or submit duplicate requests. Then improve the wording, examples, routing, or guidance connected to that behavior. Short reminders with concrete examples usually work better than a long policy announcement.
Conclusion
A successful Jira service setup begins with the service journey, not the settings screen. Define what people need, create clear request choices, assign ownership, separate meaningful workflow states, and measure the results.
But here's the truth: a portal will not solve unclear responsibilities or weak processes by itself. Test the experience with real scenarios, improve the areas that cause friction, and keep reports tied to decisions.
If your team needs a connected environment for service operations, project delivery, and knowledge work, ONES.com offers ONES Project and ONES Wiki as separate products, with deployment options for cloud and controlled environments. The right platform is the one that makes the next action clear and keeps the service promise visible.