Data Center Jira: 7 Steps to Better IT Service Workflows
Need fewer delays and clearer ownership? Discover 7 data center jira steps to streamline IT workflows, automate routing, and control change. Read now!
When a critical server fails, every minute matters. Yet many IT teams still manage incidents through scattered messages, unclear ownership, and manual handoffs.
That confusion becomes expensive in a data center. A missed approval can delay maintenance, duplicate work can interrupt service, and weak status visibility can leave stakeholders guessing.
But here’s the truth: Jira can support a reliable data center workflow when you configure it around infrastructure operations. The seven steps below show you how to organize requests, automate routing, control changes, and improve service visibility.
7 Steps to Build Better Data Center IT Service Workflows
Use these steps to turn Jira into a more consistent operating system for infrastructure support. Start with the workflow design, then add automation and reporting after the basic process works.
-
1. Map the work your data center team handles
Begin by listing the work that reaches your infrastructure team. Include incidents, access requests, hardware replacements, scheduled maintenance, capacity concerns, and security-related tasks.
Group each request by urgency, business effect, and required expertise. For example, a failed storage controller may need immediate escalation, while a planned rack inspection can follow a scheduled approval path.
Here’s why: a single generic workflow forces unrelated work through the same route. A request for a new monitoring alert should move differently from a production outage.
-
2. Create request types with clear fields
Build request types that match real infrastructure scenarios. Useful types may include production incident, maintenance request, access change, hardware issue, and capacity review.
Each type should collect the details needed for triage. A production incident might require affected service, site, severity, start time, customer impact, and current workaround.
Keep the form focused. Asking for twenty fields at intake can slow urgent reporting. Make essential fields mandatory, then collect deeper technical details during investigation.
-
3. Define ownership and escalation rules
Every request needs a clear owner. Assign work to teams such as network operations, systems engineering, facilities, security, or service desk support.
Then define escalation rules around impact and elapsed time. A critical outage may require immediate notification, while a low-priority equipment inquiry may receive a response within one business day.
For example, a ticket marked as critical and affecting multiple services can automatically move to the incident lead. The system can also notify an operations manager when the response target is at risk.
-
4. Build status flows around operational decisions
Use statuses that show meaningful progress. A practical incident flow may include New, Triaged, Investigating, Mitigating, Monitoring, and Resolved.
A maintenance request may need a different flow: Draft, Technical Review, Approval Pending, Scheduled, Executing, and Completed.
Let me explain: status names should describe a decision or action. “Waiting” gives little information. “Awaiting maintenance approval” tells the next person what must happen.
-
5. Add automation for repetitive handoffs
Automation reduces delays caused by manual coordination. You can route issues by service, location, severity, or affected team.
Useful rules include:
- Assign a network incident to the correct regional team.
- Notify the incident lead when severity changes to critical.
- Set a review reminder before a planned maintenance window.
- Escalate unresolved high-impact work after a defined period.
- Close completed requests after confirmation and a waiting period.
The best part? Automation works as a guardrail. It helps the team follow the intended process when pressure is high, while still allowing authorized staff to handle unusual situations.
-
6. Connect incidents, changes, and related work
Infrastructure problems often involve several linked activities. A network outage may create an incident, a change request, a vendor task, and a post-incident review.
Connect these items so the team can follow the full chain. Link the incident to the corrective change, attach the maintenance request to the affected service, and associate follow-up tasks with the original event.
This relationship gives managers a clearer view of cause and consequence. It also prevents the team from treating each task as an isolated event.
-
7. Measure performance and improve the workflow
Track indicators that reveal service quality. Useful measures include response time, restoration time, reopened incidents, overdue requests, change success rate, and work volume by service.
Review the results regularly. If many tickets remain in “Triaged,” the team may lack routing rules. If maintenance requests stay in approval for days, the approval path may be too complex.
Use the numbers to improve the process gradually. A short monthly review can produce practical changes, such as adding one field, adjusting one escalation rule, or removing an unnecessary approval.
How to Design a Jira Workflow for Data Center Operations
A strong workflow mirrors the way your team makes operational decisions. It should answer four questions quickly: what happened, who owns it, what happens next, and when escalation is required.
Start with the smallest workable flow. For example, an incident process may need only six statuses during the first rollout. Additional steps can follow once the team understands where delays occur.
You might be wondering: should every infrastructure team use the same flow? Usually, a shared operating model helps, while service-specific variations keep the process practical. Network incidents and facility maintenance rarely need identical approvals.
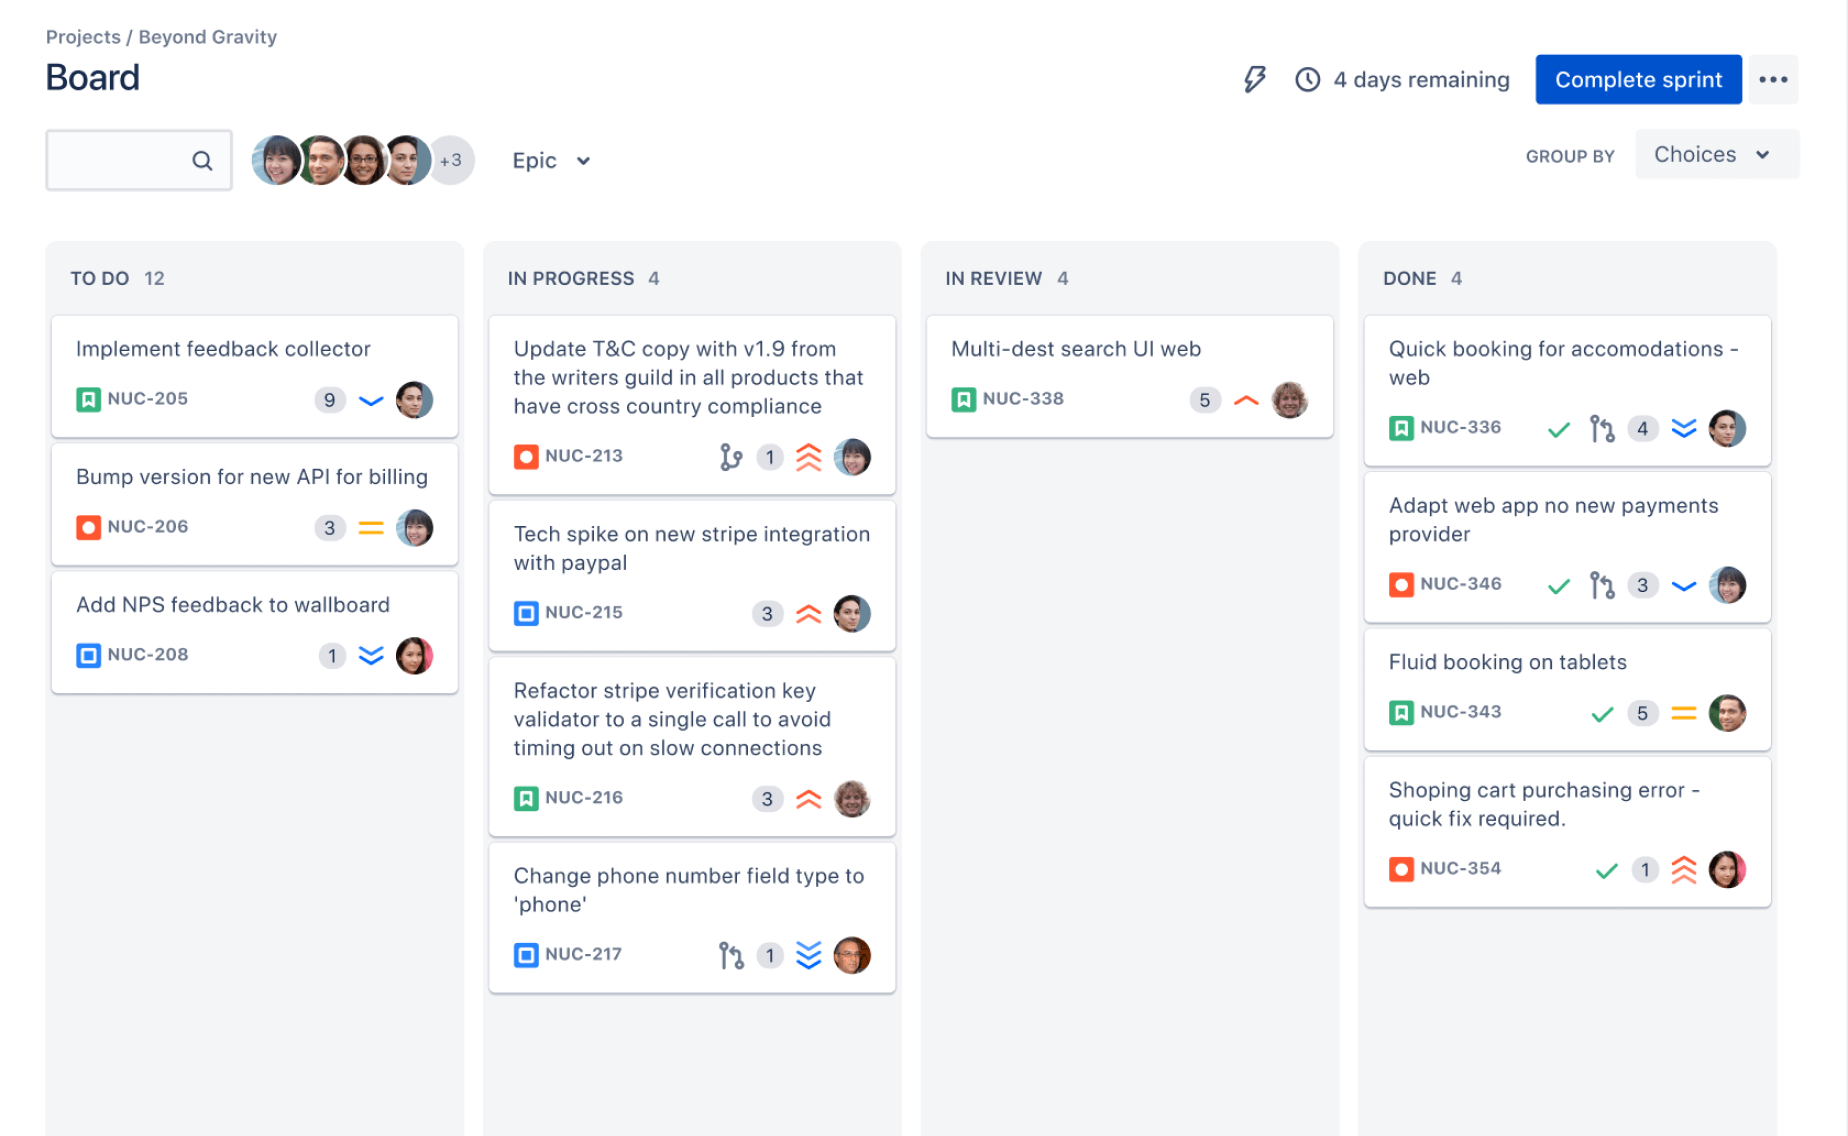
Use priority and impact together
Priority alone can create confusion. Pair it with impact so the team can distinguish an urgent issue affecting one internal service from a severe outage affecting many customers.
A simple model may use four impact levels and four urgency levels. Jira can then help calculate priority through a consistent rule instead of relying on individual judgment.
Keep approvals proportional to risk
Approval controls should reflect the potential effect of a change. A routine monitoring adjustment may need a lightweight review, while a power maintenance activity may require several stakeholders.
When every request follows the highest-control path, routine work slows down. Risk-based routing gives the team stronger control where it matters most.
Practical Examples of Infrastructure Workflows
Concrete examples make workflow design easier. Consider three common situations and the path each one could follow.
Example 1: A production network outage
An engineer reports packet loss affecting several applications. The request form captures the site, affected services, start time, severity, and current symptoms.
Jira assigns the incident to network operations, alerts the incident lead, and starts the response timer. The team records investigation notes, links related tasks, and moves the issue into monitoring after service recovery.
A follow-up review captures the cause, corrective action, and prevention plan. Management can then see both restoration performance and long-term improvement work.
Example 2: Planned rack maintenance
A facilities engineer submits a maintenance request with the planned window, rack location, affected equipment, safety considerations, and rollback plan.
The request moves through technical review and approval before scheduling. During execution, the responsible engineer records progress and raises an incident if the work produces unexpected service impact.
This approach creates a visible connection between planned maintenance and any resulting incident. That connection helps the team identify recurring risks.
Example 3: Access provisioning
An employee requests temporary access to a restricted operations area. The request identifies the person, purpose, time window, approving manager, and required access level.
Jira routes the request to the appropriate security or facilities team. Automatic reminders help prevent approvals from sitting unattended, while completion checks confirm that access ends when expected.
Reporting Metrics That Improve Service Management
Reports should support decisions rather than create more administrative work. Choose measures that show speed, reliability, workload, and risk.
| Metric |
What it reveals |
| Mean time to acknowledge |
How quickly the team recognizes and accepts an incident. |
| Mean time to restore |
How long it takes to return an affected service to normal operation. |
| Reopened incident rate |
Whether issues are being closed before the solution is stable. |
| Change success rate |
How often planned changes finish without causing service disruption. |
| Approval waiting time |
Where governance creates delays in maintenance or access work. |
| Work by service or location |
Which environments create the largest operational workload. |
For example, a rising restoration time may point to weak escalation, missing technical ownership, or incomplete troubleshooting guidance. The metric becomes useful when you connect it to a process decision.
Avoid measuring everything. Three or four reliable indicators can guide improvement more effectively than a crowded dashboard that nobody reviews.
Governance, Security, and Auditability
Data center operations require controlled access and traceable decisions. Your Jira setup should define who can create, edit, approve, transition, and close each kind of work.
Use permission schemes that match responsibilities. An engineer may update technical findings, while an approval group controls authorization for high-risk maintenance.
Keep important actions visible through transition history, comments, timestamps, and linked work. This record helps during service reviews, compliance checks, and internal investigations.
Here’s the practical balance: strong governance should make safe work easier to repeat. If controls are unclear, employees may bypass the process during urgent events.
Data Center Workflow Solution: ONES.com
Value Proposition
ONES.com brings project management and knowledge management together through ONES Project and ONES Wiki. For infrastructure teams, ONES Project can support Jira-compatible workflows with native reporting, automation, and deployment flexibility.
ONES Project is available as a Jira alternative for teams that need structured service workflows, custom process controls, and on-premise deployment options.
Core Capabilities
- Scattered incident handling → Jira-compatible workflows → Build structured incident, maintenance, access, and change flows that match established project practices.
- Manual routing → Custom workflows and fields → Capture service, location, severity, ownership, and approval details in a consistent process.
- Unclear delivery status → Sprint management → Organize improvement work, corrective actions, and infrastructure upgrades into visible work cycles.
- Repetitive coordination → Automation → Route tasks, send reminders, update fields, and escalate overdue work with less manual effort.
- Limited operational visibility → Built-in reporting → Review workload, progress, overdue tasks, and service trends without depending on many separate plugins.
- Plugin-heavy administration → Native feature parity → Keep core workflow, field, reporting, and automation functions within one platform experience.
- Deployment restrictions → Cloud, on-premise, private cloud, or air-gapped deployment → Choose an environment that fits infrastructure, security, and network requirements.
- Capacity constraints → Free plan for up to 30 seats → Give a small operations team a practical way to evaluate the platform before broader adoption.
Application Scenarios
Regional infrastructure operations: A distributed team can create separate queues for sites while using shared incident priorities and escalation rules. Managers can compare workloads across locations through consistent reporting.
Restricted-network environments: A team operating in an air-gapped environment can use a self-hosted deployment. Full feature parity between cloud and self-hosted versions helps preserve the same workflow design across deployment models.
Infrastructure improvement programs: Engineers can manage corrective actions, maintenance upgrades, and reliability initiatives in ONES Project. ONES Wiki can hold operating guidance and technical knowledge when the team also needs a knowledge management workspace.
ONES.com and ONES Project are sold separately. This lets you choose the project management or knowledge management capability that matches your immediate operating needs.
Common Challenges and Practical Solutions
Challenge: Too many request types
Solution: Begin with the work categories that create the most volume or risk. Combine similar requests until the team has enough evidence to justify a separate workflow.
Challenge: Engineers bypass the process during incidents
Solution: Make urgent reporting fast. Use a short intake form, automatic assignment, and a clear critical-incident path. Capture deeper details after stabilization.
Challenge: Approval queues delay maintenance
Solution: Separate routine, moderate-risk, and high-risk changes. Give routine work a shorter approval route while keeping stronger controls for activities with wider impact.
Challenge: Reports contain activity without insight
Solution: Link every report to a management question. For example, use overdue work to decide whether staffing or routing needs adjustment.
Challenge: Knowledge disappears after resolution
Solution: Add a review step for major incidents. Capture the cause, response, prevention action, and owner so future engineers can apply the learning.
FAQs
Can Jira support data center incident management?
Yes. Jira can support incident intake, prioritization, routing, escalation, collaboration, and reporting when the workflow is configured for infrastructure operations. Create request types for common events, define ownership, and connect incidents with corrective actions. Your team should also establish clear permissions and escalation rules so urgent work receives attention without weakening operational control.
What fields should an infrastructure incident include?
Start with affected service, location, severity, impact, start time, reporter, current symptoms, and assigned team. You can add technical details during investigation. For high-impact incidents, include customer effect, communications owner, workaround, recovery time, and follow-up action. Keep the initial form short enough for fast reporting during an outage.
How many statuses should a data center workflow have?
Use enough statuses to show meaningful decisions without creating administrative friction. A basic incident flow may need six stages, while a high-risk maintenance process may need more approval and execution steps. Review the workflow after several weeks. If people skip statuses or use the same status for different situations, simplify the design.
Should incidents and changes use the same workflow?
They usually need related workflows with different purposes. Incidents focus on restoring service quickly, while changes focus on controlling planned modifications. Link the two when a corrective change follows an incident. This keeps response work moving while preserving approval and risk controls for the planned activity.
Is a self-hosted platform useful for restricted environments?
Yes. Self-hosted deployment can suit teams with strict network, security, or residency requirements. An air-gapped environment may need a platform that operates without public network access. Before choosing a deployment model, confirm feature availability, administration responsibilities, update procedures, and integration requirements.
Conclusion
Better infrastructure service management begins with a clear workflow. Map the work, create focused request types, assign ownership, define meaningful statuses, automate repetitive handoffs, connect related activities, and review performance.
But here’s the truth: a tool cannot repair an unclear process by itself. Your team needs practical rules that fit real incidents, maintenance windows, access requests, and improvement work.
When outages create confusion, the solution is a visible operating path with clear decisions and accountable owners. Jira can support that approach, while ONES.com offers another platform path for teams seeking Jira-compatible project workflows across cloud, on-premise, private cloud, or air-gapped environments.