Jira Service Management: A 7-Step Guide for Modern IT Teams
Struggling to manage IT requests? This 7-step jira services management guide streamlines workflows, priorities, and service quality. Read now to learn how.
IT teams often inherit a service desk that feels busy yet remains difficult to manage. Requests arrive through email, chat, and hallway conversations. Incidents lose priority, approvals stall, and technicians spend valuable time asking for missing details.
That disorder becomes expensive as your organization grows. A minor access request can trigger several messages, while a serious outage competes for attention with routine password resets. Without a clear workflow, managers also struggle to measure service quality.
But here's the truth: Jira Service Management can bring those requests into one structured service environment. You can organize portals, queues, approvals, automation, knowledge resources, and reporting around the way your team actually works.
This seven-step guide shows you how to plan and improve a Jira Service Management setup without overwhelming your technicians or employees.
How to Set Up Jira Service Management in 7 Steps
Jira Service Management is Atlassian's service management platform for handling requests, incidents, problems, changes, and other support workflows. A successful setup connects employee needs with clear intake, prioritization, ownership, communication, and measurement.
Follow these seven steps in order. Each step creates a practical foundation for the next one.
-
Define the Services You Support
Start by listing the services your team provides. Examples include employee access, hardware support, software provisioning, customer assistance, infrastructure monitoring, and security reviews.
For each service, clarify who requests it, who fulfills it, what information is required, and how quickly the team should respond. This prevents your portal from becoming a confusing collection of unrelated request types.
For example, “request software access” should identify the application, business reason, manager, requested access level, and required date. A technician can then act without several follow-up messages.
-
Choose the Right Project and Service Templates
Create separate service areas when teams have different responsibilities, approval paths, or customer groups. An internal IT service project may need employee-facing requests, while a customer support project may require external communication and service-level tracking.
Use a suitable Jira Service Management template as a starting point. Then remove unnecessary request types and rename categories so they match the language your audience already uses.
Here's why: familiar wording improves adoption. Employees are more likely to select “Get access to an application” than “Identity and entitlement administration.”
-
Design the Request Portal Around User Intent
Organize the portal around what people want to accomplish. Group requests into clear categories such as Access, Devices, Accounts, Software, Workplace Services, and Report an Issue.
Keep each request form focused. Ask for information that helps resolve the request, while avoiding fields that create unnecessary effort. Conditional fields can reveal additional questions only when they apply.
For example, a “Report a laptop problem” form might ask whether the device starts, connects to the network, or shows an error. A simple troubleshooting prompt may solve a problem before a technician gets involved.
-
Build Workflows, Queues, and Ownership Rules
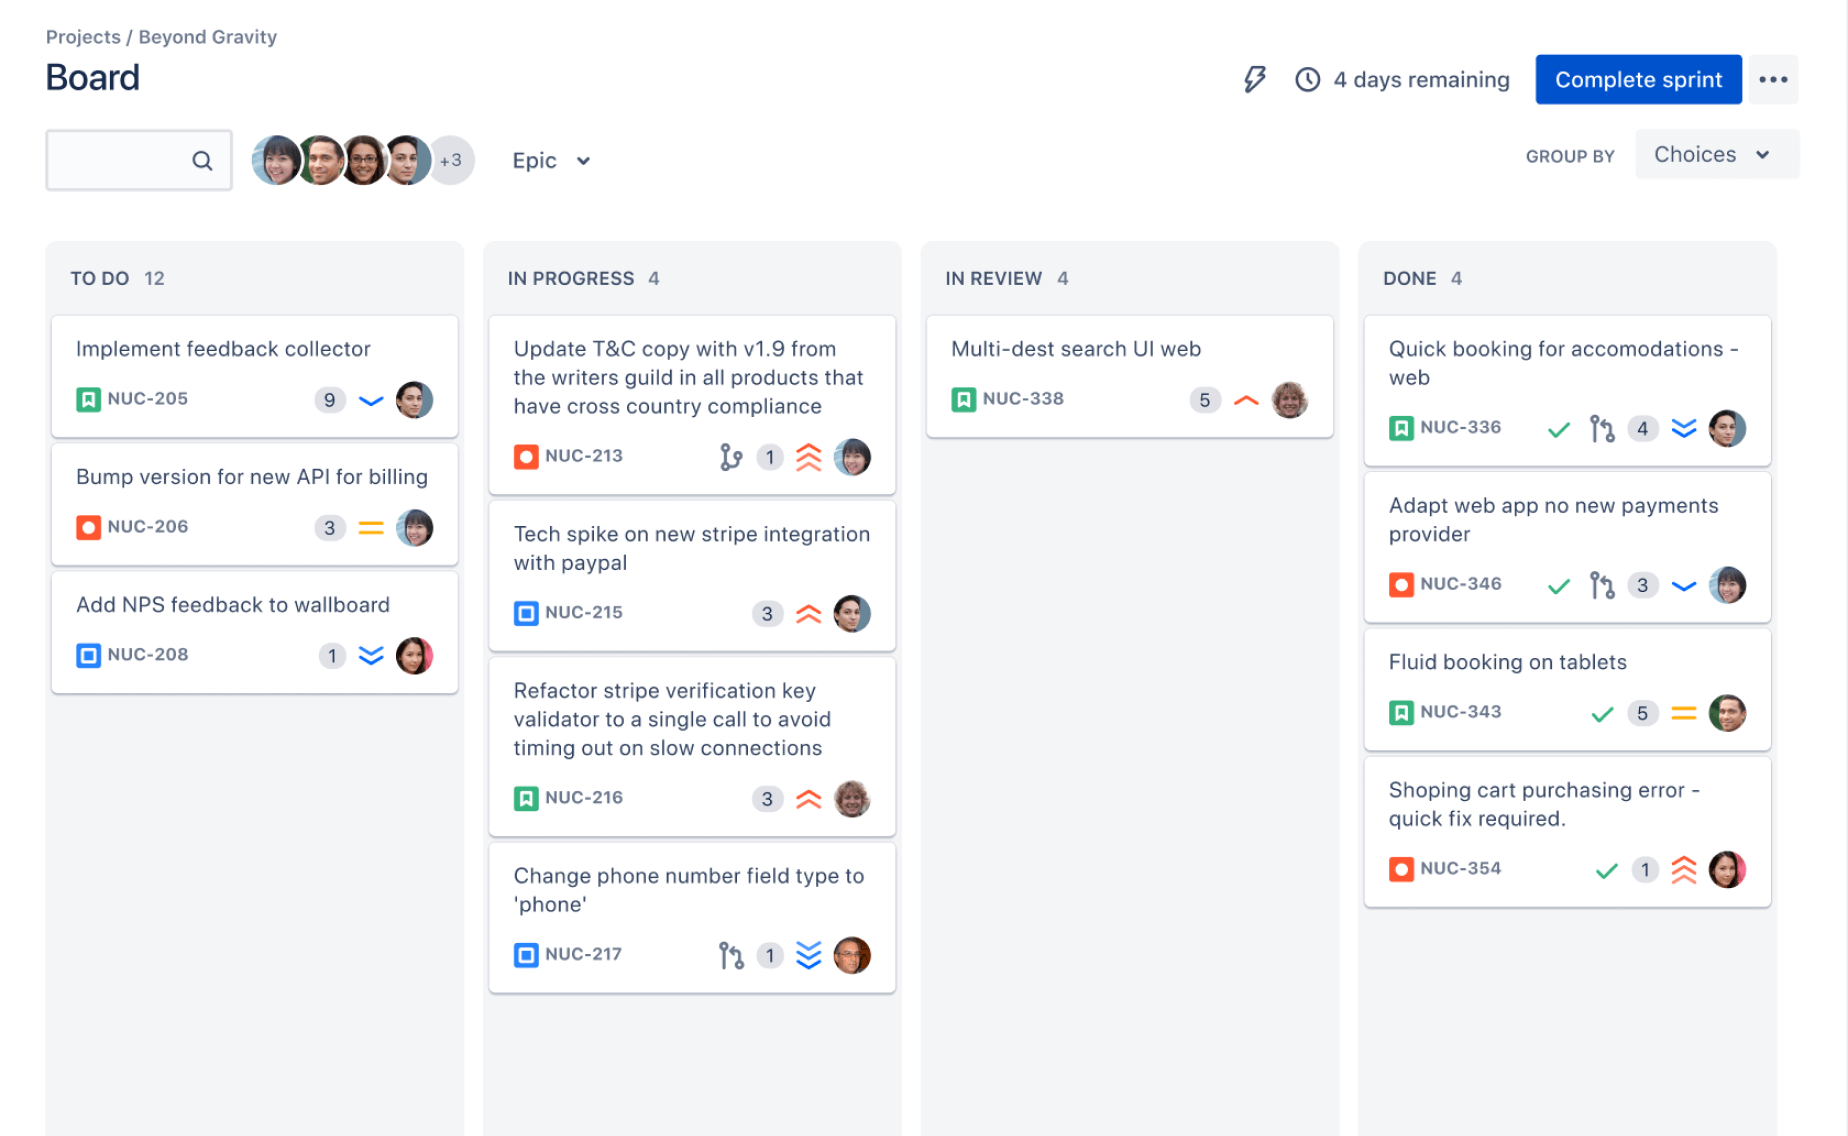
Map the lifecycle of each major request type. A basic access request may move through Open, Waiting for Approval, In Progress, Waiting for Requester, and Resolved.
Assign ownership at each stage. A request should have a visible responsible team or technician, even when another person must approve or provide information.
Queues help technicians focus their attention. Useful queues include urgent incidents, requests awaiting approval, overdue work, unassigned items, and requests approaching their service target.
Let me explain: a workflow describes movement, while a queue creates operational focus. You need both to keep work moving consistently.
-
Configure Service Levels, Priorities, and Escalations
Set service targets according to business impact. A critical outage affecting an entire department deserves faster attention than a routine equipment request.
Define priority using practical factors such as urgency, affected people, operational impact, and available workaround. Give technicians examples so they can classify work consistently.
Configure alerts before targets are missed. For example, an unresolved high-impact incident could notify an incident manager after 30 minutes and a service owner after 60 minutes.
Service levels become useful when they guide behavior. A dashboard showing 95 percent compliance is less valuable if technicians cannot see which requests need attention next.
-
Automate Repetitive Service Work
Automation can assign requests, add labels, send reminders, update status, and notify the right people. Start with repeatable tasks that consume time without requiring judgment.
Examples include assigning printer requests to workplace technology, reminding an approver after two business days, and closing a request after a defined period without a response.
Introduce automation gradually. Test each rule with representative requests, then monitor whether it creates duplicate alerts, incorrect assignments, or premature closures.
The best part? Small automations often deliver visible gains quickly. A routing rule that saves five minutes across 100 monthly requests returns more than eight hours of team capacity.
-
Measure Results and Improve the Service
Review performance through a combination of operational and experience measures. Useful indicators include request volume, resolution time, reopened requests, breached service targets, customer satisfaction, and incident recurrence.
Look for patterns rather than isolated results. If access requests take longer every month, the issue may involve approval delays, incomplete forms, or unclear ownership.
Run a monthly service review with technicians and service owners. Choose one improvement, such as simplifying a form or adding a knowledge article, and measure the effect during the next review period.
What Jira Service Management Helps You Manage
Jira Service Management brings several service practices into a shared workspace. Its primary use cases include service requests, incident response, problem investigation, change enablement, and knowledge-centered support.
Service requests cover routine needs such as account access, equipment, permissions, and software. Incidents focus on restoring service when something breaks. Problems examine recurring causes, while changes manage planned modifications with appropriate review.
You can also connect service work with development and operations activities. For example, an incident may reveal a defect, create a development task, and link the eventual fix to the service record.
Service Requests
A request catalog gives employees a predictable way to ask for help. Each request type can include its own fields, approvals, workflow, assignment logic, and service target.
Consider a new employee onboarding request. It may trigger tasks for accounts, hardware, building access, and team permissions. Coordinating these activities in one process reduces missed handoffs.
Incident Management
Incident workflows help teams assess impact, coordinate response, communicate updates, and restore normal service. A major incident process may include an incident commander, communication lead, technical lead, and post-incident review.
Clear roles matter during pressure. When everyone knows who coordinates the response, technicians can concentrate on diagnosis and recovery rather than debating ownership.
Change and Problem Management
Changes can be reviewed according to risk. A low-risk, repeatable change may follow a lightweight path, while a high-impact infrastructure change may require additional approval and scheduling.
Problem management connects recurring incidents to deeper investigation. If the same network failure occurs every Friday, the team can track the pattern and address the underlying cause.
How to Build Better Service Workflows
A strong workflow mirrors real work while keeping the number of decisions manageable. Begin with the current process, identify delays, and remove steps that add no control or useful information.
For example, imagine an employee requesting access to a project system. The workflow may include requester submission, manager approval, security review, technical fulfillment, and confirmation. Each stage has a clear owner and completion condition.
Use status names that people understand. “Waiting for Security Review” communicates more than “Pending,” especially when a request remains paused for several days.
Compare the process before and after implementation. If technicians previously searched three channels for request details, a structured portal should reduce that search time. If approvals still happen through informal messages, the workflow needs further refinement.
Keep Forms Focused
A form with 20 required fields may appear thorough, yet it can discourage accurate submissions. Ask for the information needed to make the next decision, then gather additional details later when necessary.
For a VPN issue, ask about the location, device, connection type, error message, and business impact. Avoid requesting unrelated information that the technician cannot use.
Make Ownership Visible
Every active request should show its current owner or responsible team. Shared queues work well when assignment rules are clear and technicians regularly review unassigned work.
Visible ownership also improves communication. A requester can see whether the task is awaiting approval, under technical review, or waiting for their reply.
How to Improve Adoption Across Your Organization
Technology alone does not create a reliable service experience. People need to understand where to ask for help, what information to provide, and how they will receive updates.
Launch with a small group first. Choose a department that submits frequent requests, test the portal for two weeks, and collect examples of confusing labels or missing fields.
You might be wondering: should you keep email available? A practical approach is to support email during transition while guiding people toward the portal. Then review which requests still arrive by email and improve the corresponding portal experience.
Explain the benefit in concrete terms. “Use this portal to check status without sending a follow-up message” is more persuasive than “The new system improves efficiency.”
Use Knowledge at the Right Moment
Place helpful articles near related request types. A password reset article can appear when someone begins an account access request, while a network troubleshooting guide can support a connectivity form.
Keep articles short and task-oriented. A useful guide should tell someone what to check, what result to expect, and when to contact the service team.
Train Technicians on the Operating Model
Technicians should understand priority rules, queue ownership, escalation timing, and communication expectations. A short weekly review can reinforce these habits better than one long training session.
Use real examples from the first month. Review a delayed approval or incorrectly prioritized incident, then adjust the workflow or guidance where the confusion began.
Metrics That Show Whether Service Is Improving
Choose metrics that help you make decisions. Volume tells you where demand is concentrated, while resolution time shows how quickly work moves through the service.
Customer satisfaction adds an experience perspective. A request resolved quickly may still create frustration if the requester receives no explanation or must repeat details several times.
Use a balanced view rather than chasing one number. Reducing average resolution time can produce poor outcomes if technicians close requests before the issue is actually resolved.
| Metric |
What it can reveal |
| Request volume |
Which services create the most demand and where self-service may help |
| First response time |
How quickly the service team acknowledges new work |
| Resolution time |
How long requests take to complete across different categories |
| Reopened requests |
Whether technicians are closing work before the underlying need is satisfied |
| Service target breaches |
Where workload, routing, staffing, or approval delays require attention |
| Customer satisfaction |
How requesters perceive communication and outcome quality |
Review metrics by request type, team, priority, and time period. A single average can hide the fact that routine requests perform well while urgent incidents remain poorly coordinated.
For example, if 80 percent of software requests meet their target but approval delays cause most breaches, the improvement may belong in the approval path rather than the technician queue.
Jira Service Management Solution: ONES.com
Value Proposition
ONES.com is a unified platform for project management and knowledge management, powered by ONES Assistant. ONES Project provides project management capabilities and can serve as a Jira alternative for teams that want service-related work, development activities, and delivery planning in one environment.
ONES Project and ONES Wiki are sold separately, allowing you to choose the capabilities that match your operating model. The platform supports cloud, on-premise, private cloud, and air-gapped deployments, with full feature parity between cloud and self-hosted versions.
Core Capabilities
- Scattered service and delivery work: Jira-compatible workflows in ONES Project connect service activities with development and delivery tasks, helping teams follow work across stages.
- Limited visibility into progress: Built-in reporting gives managers views of status, workload, progress, and delivery trends without assembling separate reporting processes.
- Rigid request handling: Custom workflows and fields let teams reflect approval steps, technical reviews, ownership rules, and service categories.
- Manual sprint coordination: Sprint management helps teams plan support improvements, recurring maintenance, and development work within structured iterations.
- Repetitive administrative work: Automation can handle routing, status transitions, reminders, and other predictable actions, reducing routine coordination.
- Too many extensions: Native capabilities can reduce dependence on multiple plugins when teams need workflows, fields, reporting, and planning in one environment.
- Restricted deployment requirements: On-premise, private cloud, and air-gapped options support organizations that cannot place operational work in a public cloud environment.
- Fragmented knowledge: ONES Wiki provides a knowledge base option for service instructions, troubleshooting guidance, policies, and team practices.
Application Scenarios
Internal IT support: An IT team can manage access requests, equipment issues, incidents, and recurring improvements through structured workflows. ONES Wiki can provide troubleshooting guidance alongside the work environment when purchased separately.
Product and engineering support: A support team can capture customer issues, connect them with development work, and monitor delivery progress. Custom fields can record product area, severity, affected release, and customer impact.
Restricted-network operations: A regulated organization can use an on-premise or air-gapped deployment while retaining the same core capabilities available in the cloud version. This supports controlled environments where network separation is part of operational policy.
Common Challenges and Practical Solutions
Challenge: Too Many Request Types
Solution: Group related needs into understandable categories and retire request types that receive little use. Review the portal after launch and combine overlapping options.
Challenge: Unclear Priority Rules
Solution: Define priority with impact and urgency examples. “One employee cannot access a tool” should differ from “an entire department cannot perform a core business process.”
Challenge: Approval Delays
Solution: Add reminders, backup approvers, and escalation rules. Track how long requests wait for approval separately from technical work.
Challenge: Poor Knowledge Maintenance
Solution: Assign an owner and review date to important guidance. Update an article whenever a recurring request reveals unclear or outdated instructions.
Challenge: Automation That Creates Confusion
Solution: Introduce one rule at a time and test its effect. Keep an audit trail of changes so the team can identify why a request moved or received a notification.
FAQs
Is Jira Service Management suitable for a small IT team?
Yes. A small team can start with a limited catalog, a few queues, and simple workflows. Begin with high-volume requests such as access, equipment, and password support. As demand grows, add automation, service targets, knowledge guidance, and incident practices. A small implementation is easier to maintain than a complex setup built before the team understands its real operating needs.
What should I configure first?
Start with services, request types, ownership, and priority rules. These elements determine how work enters the team and how technicians decide what to handle next. After the basic flow works, add service targets, automation, approvals, and reporting. Test the setup with real examples before making it available to the entire organization.
How many fields should a service request contain?
Include the fields needed to route, prioritize, approve, and resolve the request. For example, an access request may need the application, requester, access level, business reason, and manager. Avoid collecting details that no one uses. If technicians regularly ask the same follow-up question, consider adding that field after confirming it improves completion speed.
How can I reduce repeated support questions?
Identify requests that appear frequently and create short guidance for them. Link that guidance near the relevant request form and review search terms that produce poor results. If people still submit the same request after reading an article, the instructions may need clearer steps, better screenshots, or a direct action path.
Should incidents and service requests use the same workflow?
They can share some statuses, yet their goals differ. A service request usually follows fulfillment and approval steps, while an incident focuses on restoring normal service quickly. Separate workflows make these differences visible. You can still report on both through common measures such as ownership, response time, resolution time, and customer satisfaction.
Conclusion
A reliable Jira Service Management environment starts with a clear service catalog and continues through focused forms, visible ownership, practical workflows, service targets, automation, and regular measurement.
But here's the truth: configuration alone will not fix unclear responsibilities or confusing request paths. Your team must connect each workflow to a real business need and improve it using evidence from daily work.
Start with seven steps: define services, select suitable templates, design the portal, build workflows, set priorities, automate repetitive tasks, and review results. When employees know where to ask, technicians know what to do, and managers can see the outcomes, service becomes easier to improve.