Jira Spikes Explained: Purpose, Examples, and Uses in Agile
Unsure what is a spike in Jira? Explore its purpose, examples, and Agile uses to reduce uncertainty—read now and plan smarter.
A Jira spike is a time-boxed research or experiment task that helps an Agile team reduce uncertainty before committing to a solution. It gives you room to investigate a question that could affect a story, estimate, or technical decision.
Without a clear spike, teams may guess at complex work and discover the risks halfway through a sprint. That can lead to missed commitments, rushed fixes, or stories that are too large to estimate confidently. A spike can help, but only when its purpose and time limit are clear. But here's the truth: a spike is not an open-ended research assignment. You define a question, set a limit, capture what you learn, and agree on the next step. Here’s how that works in Jira, with examples you can adapt for your team.
What a Spike Means in Jira
In Agile, a spike is a short, focused investigation used to answer a question or test an approach. In Jira, teams track that work as an issue, often using a custom issue type named “Spike.”
Jira does not require every project to use a dedicated Spike issue type. Your team may instead use a task with a label, component, or workflow that identifies exploratory work. The important part is that the issue makes the investigation visible and manageable.
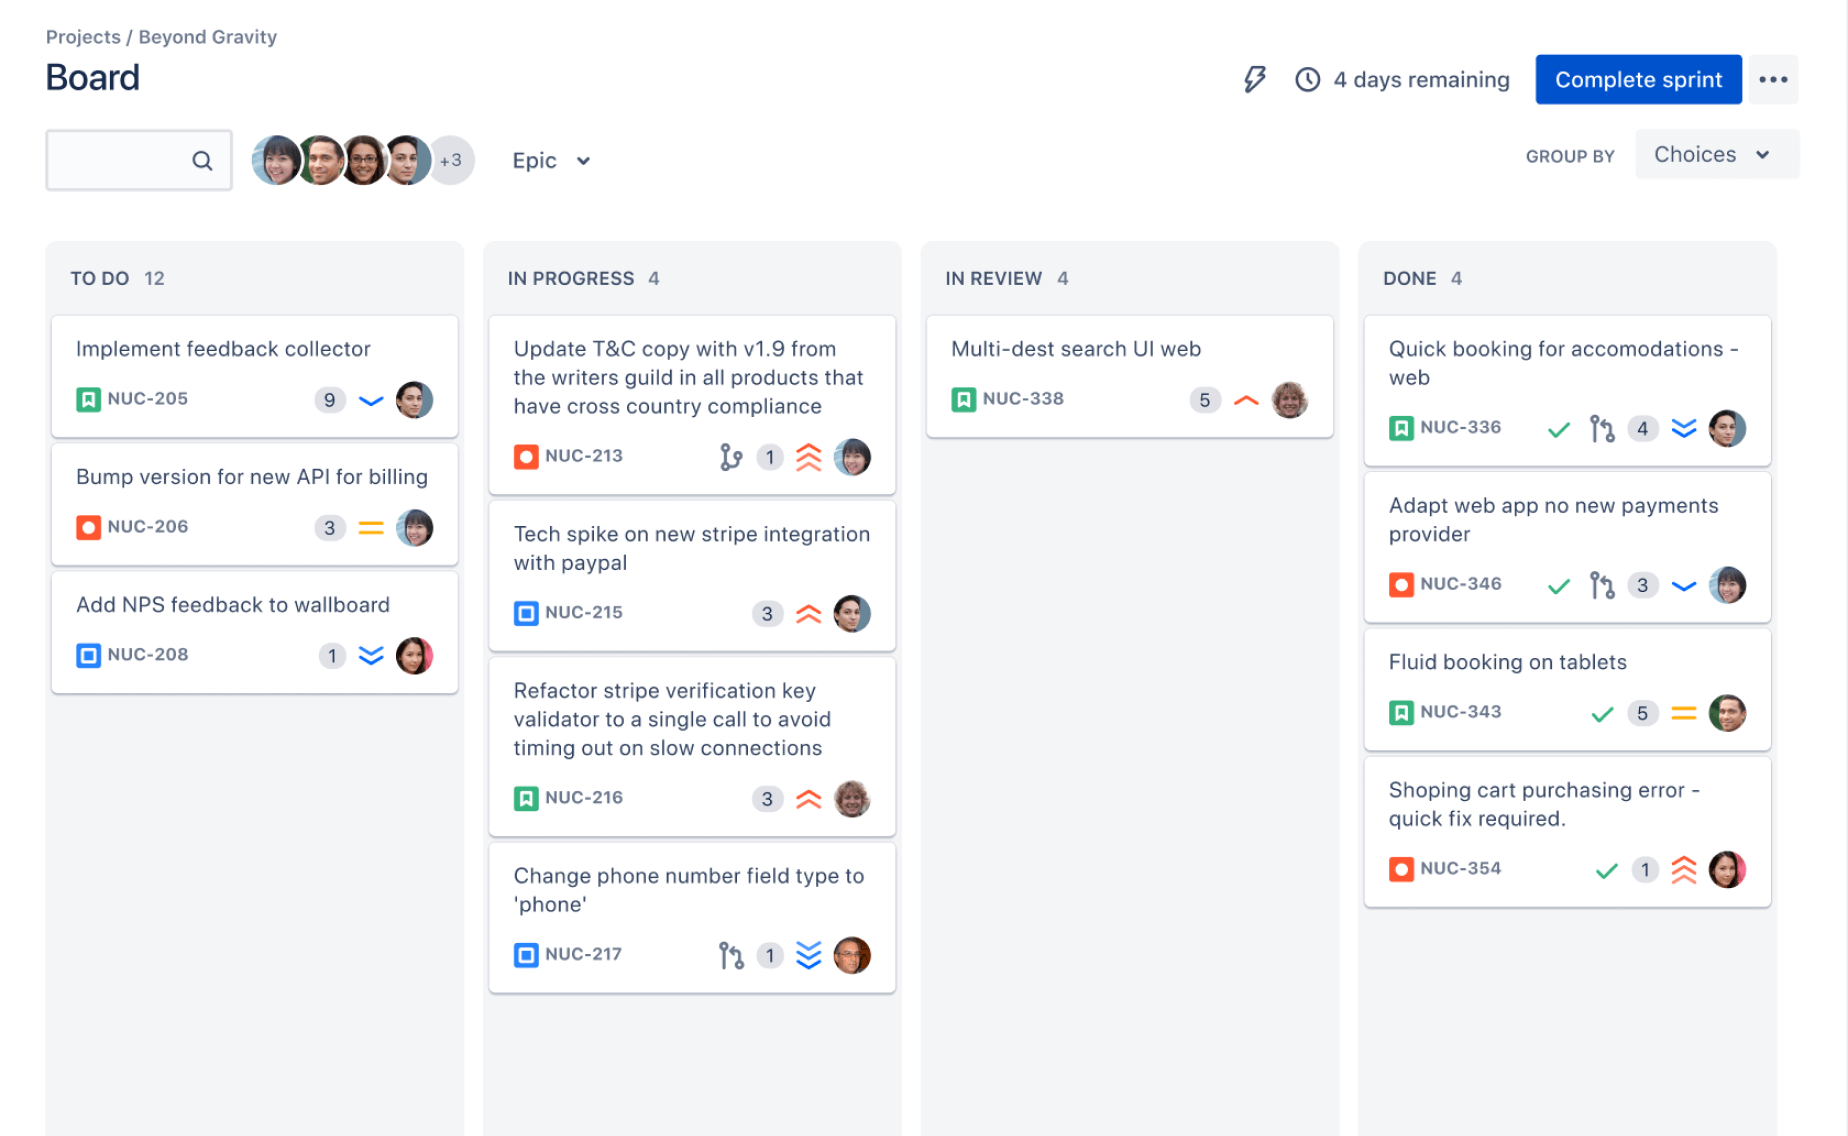
What a useful spike includes
- A specific question: For example, “Can our payment service support recurring billing through the current API?”
- A time limit: Set a fixed duration, such as four hours or one day, so exploration stays bounded.
- A clear outcome: State what the team needs to learn, test, or recommend.
- A follow-up decision: Explain whether the result should lead to a story, a technical change, or another investigation.
Here's why: an issue called “Research payment integration” can expand endlessly. A spike that asks whether recurring billing works with the existing API gives the team a concrete question to answer.
How a spike differs from related Jira work
A story describes value or functionality the team intends to deliver. A task tracks work with a known outcome, while a bug records behavior that needs correction. A spike focuses on learning when the team does not yet know enough to estimate or plan the delivery work.
These categories can overlap in a workflow. For example, a team might use a task issue type for a spike and distinguish it with a label. The issue type matters less than shared team understanding of the work and its expected result.
Why Agile Teams Use Spikes
Teams use spikes when uncertainty makes a delivery estimate unreliable or when a decision could change the implementation. A brief investigation can reveal technical constraints before the team commits to a larger story.
Suppose a team needs to add sign-in through an external identity provider. A spike can test the authentication flow, check required permissions, and identify security questions. The next sprint plan can then reflect what the team actually learned.
The best part? A spike can prevent a small unknown from becoming a large surprise. It gives the team a defined place to investigate before planning delivery work in detail.
When a spike is worth creating
- The team has several plausible technical approaches and needs evidence to choose one.
- A new service, API, or platform has unclear limits or compatibility requirements.
- The team cannot estimate a story because a key dependency is unknown.
- A performance, security, or accessibility concern needs a targeted test.
A spike is less useful when the team already knows the approach and can move directly into implementation. In that case, ordinary delivery work may be easier to plan and review.
Jira Spike Examples You Can Adapt
Concrete questions help you distinguish a productive spike from a vague research task. Each example below gives the team a bounded investigation and a result it can use.
Integration feasibility
Question: Can the current billing service handle recurring payments through the provider’s API?
Timebox: One working day. Outcome: A small test of the key API call, a list of integration constraints, and a recommendation about the next implementation step.
Performance investigation
Question: Can the product’s search endpoint meet the agreed response-time target with the expected request volume?
Timebox: Half a day. Outcome: A repeatable performance test, observed bottlenecks, and a decision about whether optimization work needs a separate story.
Estimation uncertainty
Question: What work is required to migrate existing customer permissions to the new access model?
Timebox: Four hours. Outcome: A breakdown of the migration risks, affected areas, and follow-up stories that the team can estimate.
Let me explain: these spikes do not promise finished product functionality. They produce enough learning for the team to make a better delivery decision.
How to Create and Manage a Spike in Jira
Keep the issue focused from creation through review. A short workflow makes it easier to see why the team needs the investigation and what should happen after it.
- Write the question. Describe the uncertainty in one sentence. Replace “Explore caching” with “Would caching reduce repeated catalog requests without serving stale prices?”
- Set the timebox. Choose a limit that matches the scope. If the team cannot answer the question within that limit, the issue should identify what decision is needed next.
- Define the result. Say what the team will share, such as a recommendation, test result, prototype, or list of follow-up work.
- Connect related work. Link the spike to the story, epic, or decision it supports. This gives teammates context when they review its outcome.
- Review the findings and plan next steps. At completion, discuss what the team learned and create delivery issues for any confirmed work.
In Jira, your team can use a dedicated issue type if its project configuration supports one. Otherwise, a task plus a “spike” label or a custom field can make the work easy to find and report.
Choose an estimation approach deliberately
Teams handle spike estimates differently. Some track the timebox in hours and exclude the spike from story-point velocity; others include it in sprint planning under an agreed convention. Either approach can work when the team applies it consistently.
A useful rule is to avoid treating the spike’s estimate as an estimate for the delivery story. A four-hour investigation may reveal a two-day implementation—or a much larger effort.
Common Challenges with Agile Spikes
Spikes can lose their value when the team leaves the question, limit, or follow-up vague. A few simple practices help keep the investigation useful and visible.
- Problem: The scope keeps expanding. Solution: Tie the work to one decision and pause when the timebox ends. Create another spike only if a new question genuinely remains.
- Problem: The issue produces no shareable result. Solution: Specify the expected outcome before work starts, such as a test result, recommendation, or list of risks.
- Problem: The team treats the spike as a delivery estimate. Solution: Use the findings to create and estimate implementation work separately.
- Problem: Nobody knows why the investigation happened. Solution: Link the spike to the related story or epic and summarize the decision it informed.
- Problem: The team creates spikes for routine work. Solution: Check whether the outcome is already known. If it is, track the work as a regular task or story.
ONES.com Solution: Managing Spike Work Alongside Delivery
When exploratory work sits beside sprint commitments, teams need a clear way to connect investigation, delivery, and shared knowledge. ONES.com is a unified project management and knowledge management platform powered by ONES Assistant. ONES Project handles project management and is a Jira alternative; ONES Wiki provides knowledge management as a Confluence alternative. They are sold separately.
For teams that track spikes, the practical value is in organizing the issue, managing its sprint context, and carrying findings into follow-up work. ONES Project supports Jira-compatible workflows, custom fields, reporting, automation, and sprint management. It is available in cloud and self-hosted deployments, including on-premise, private cloud, and air-gapped options, with feature parity between cloud and self-hosted versions.
Core capabilities for spike workflows
- Spike work is hard to identify: Custom workflows and fields in ONES Project let teams mark exploratory work clearly, helping teammates distinguish it from delivery issues.
- Investigation lacks a clear status: Custom workflows can reflect stages such as planned, investigating, and reviewed, so the team can see where a spike stands.
- Related work gets disconnected: Jira-compatible issue workflows help teams manage connections between spikes and the stories or epics they inform.
- Sprint planning misses exploratory effort: Sprint management gives teams a place to plan and review spike work alongside other sprint commitments.
- Repeated process steps create overhead: Automation can handle routine workflow actions, reducing manual updates when issues move through agreed stages.
- Teams lack visibility into investigation work: Built-in reporting helps teams review issue progress and workload without relying on a collection of add-ons.
- Default issue details do not fit the team: Custom fields let teams capture details such as the question, timebox, or expected outcome in a consistent way.
- Teams want fewer separate extensions: Core project management capabilities can reduce reliance on plugins for common workflow, sprint, and reporting needs.
- Restricted environments limit deployment options: Cloud, on-premise, private cloud, and air-gapped deployments give organizations choices that match their operating requirements.
Where teams might apply it
A software team could create a spike issue to test a new API integration, use a custom field to record its time limit, and link the result to an implementation story. Sprint planning and reporting help the team track that investigation beside committed delivery work.
A team in a restricted network could manage exploratory work in an on-premise or air-gapped deployment. If it also needs a connected knowledge base, ONES Wiki can be considered separately from ONES Project.
ONES.com may suit teams looking for Jira-compatible project management with deployment flexibility and built-in capabilities. The fit depends on the team’s workflow, hosting requirements, and need for project and knowledge management.
FAQs About Spikes in Jira
Is “Spike” a standard Jira issue type?
Jira projects do not all use the same issue types, and a Spike issue type may need to be added or configured by a project administrator. Some teams instead track exploratory work as a task and apply a label or custom field. Agree on a team convention so people can recognize spike work in boards, searches, and reports.
Should a spike have story points?
There is no single estimation rule that fits every Agile team. Some teams estimate spikes in hours and keep them separate from story-point velocity. Others include them in sprint planning under a consistent local convention. Whichever method you choose, keep the spike estimate separate from the delivery estimate, because the investigation may change the implementation scope.
How long should a Jira spike last?
Choose a timebox that fits the question, such as a few hours or one working day. A longer investigation may be appropriate when the team has a substantial unknown, but split the work if it becomes difficult to review. When the time limit ends, share what you learned and decide whether another investigation is justified.
What should happen when a spike is complete?
Review the result with the people who need it, then decide what the learning means for delivery. The team might create implementation stories, update an estimate, choose an approach, or identify a remaining risk. Close the spike when its agreed outcome is available and its follow-up work is clear.
Can a spike include coding?
Yes. A spike can include a prototype, test, or small technical experiment when that work answers the investigation question. The team should clarify whether the code is exploratory or intended for production. If the prototype reveals a useful approach, create and estimate the production work separately rather than assuming the experiment is ready to ship.
Conclusion
A Jira spike is a time-limited way to answer a question that could affect planning or delivery. Define the uncertainty, set a boundary, agree on a useful outcome, and connect the investigation to the work it informs.
When teams let a spike remain open-ended, uncertainty can simply become untracked effort. A focused investigation gives you a practical path from “we don’t know yet” to a decision the team can act on. Use Jira conventions that suit your workflow, and make the learning visible before moving into implementation.