Jira Support: A Practical Guide to Faster Issue Resolution
Still losing time on unresolved tickets? This Jira support guide streamlines intake, triage, escalation, and resolution. Click to learn faster fixes.
Jira can track almost anything, yet unresolved tickets still pile up. A vague request, missing context, or unclear ownership can turn a simple fix into a week-long exchange.
The frustration grows quickly. Customers wait, developers lose focus, and support agents spend more time chasing details than solving problems. Even a well-configured Jira project can slow down when its support process lacks structure.
Here’s the practical solution: create a clear intake, triage, escalation, communication, and review workflow. This guide explains how Jira support works, how to resolve issues faster, and how to avoid the bottlenecks that make support feel harder than it should.
What Jira Support Includes
Jira support is the process of receiving, organizing, investigating, prioritizing, and resolving technical issues through Jira. It connects support requests with the teams responsible for fixing them.
A reliable support process usually covers five activities:
- Capturing the issue with enough detail to begin investigation.
- Classifying the request by type, urgency, product area, and impact.
- Assigning ownership to the right person or team.
- Tracking communication, progress, escalation, and resolution.
- Reviewing recurring problems to prevent repeat incidents.
Jira may support internal service teams, customer-facing support teams, software developers, or a combination of all three. The workflow changes slightly, but the goal remains consistent: move each issue toward a useful resolution with minimal delay.
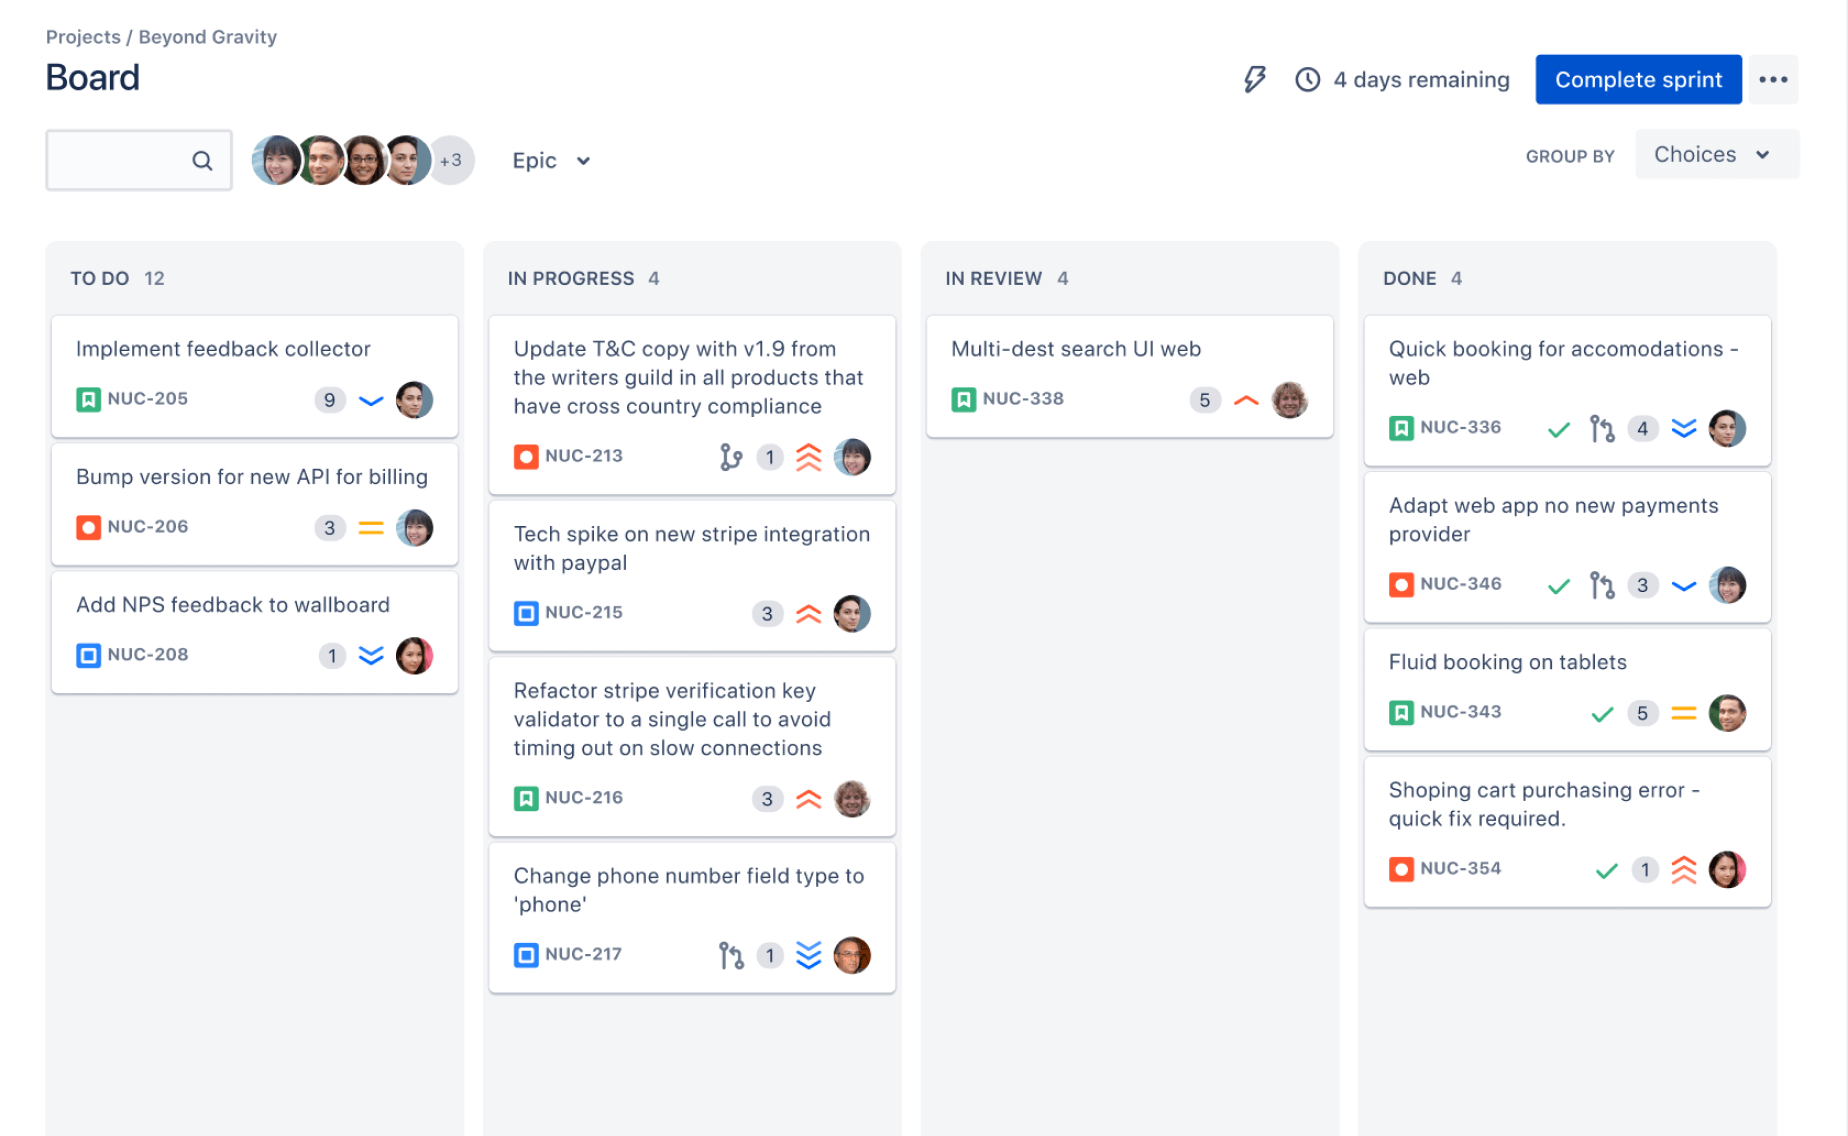
The Main Parts of a Support Workflow
A support workflow is more than a queue of tickets. It is a series of decisions that determine what happens next.
| Workflow area |
Practical purpose |
| Intake |
Collect the requester’s problem, environment, impact, and contact details. |
| Triage |
Confirm the issue, remove duplicates, and assess urgency. |
| Assignment |
Send the request to a team or specialist with the right responsibility. |
| Investigation |
Reproduce the problem, identify contributing factors, and test possible fixes. |
| Communication |
Keep the requester informed about progress, delays, and next steps. |
| Resolution |
Apply the fix, confirm the outcome, and record the final explanation. |
| Review |
Identify trends, recurring defects, and process improvements. |
When one area is weak, the whole process slows down. For example, poor intake creates repeated questions, while unclear assignment creates idle time.
Jira Service Management and Jira Software
Jira Service Management is designed for service workflows, including request portals, service queues, approvals, and service-level tracking. Jira Software focuses more heavily on development planning, issue tracking, and delivery.
Many organizations connect both products. A service agent can raise a development issue when a customer reports a defect. The development team then investigates the defect while the support team manages customer communication.
Here’s why that connection matters: the customer should not need to understand your internal team structure. Their request should progress smoothly, even when several specialists become involved.
How to Build a Faster Issue Resolution Process
The fastest support teams do not simply ask people to work harder. They reduce uncertainty at each stage of the workflow.
1. Define What Belongs in the Queue
Start by deciding which requests should enter Jira support. Include incidents, access problems, product defects, configuration questions, and service requests when your team handles them.
Create separate request types when the required information differs. A password issue needs different details from a performance problem or a suspected software defect.
For example, a performance request may ask for:
- The affected product area.
- The approximate time of the slowdown.
- The number of affected people.
- The user’s location or operating environment.
- Recent changes before the issue appeared.
Clear boundaries prevent the queue from becoming a general inbox for every unrelated question.
2. Design a Useful Intake Form
An intake form should collect information that helps someone make the next decision. Every unnecessary field increases completion time without improving resolution quality.
Use plain language instead of internal terms. Ask, “What stopped working?” rather than, “Describe the affected component.”
Useful fields often include:
- A short summary.
- A detailed description.
- Business or customer impact.
- Urgency and desired response time.
- Steps that reproduce the problem.
- Expected behavior and actual behavior.
- Relevant account, device, browser, or environment details.
- Related request numbers.
Let me explain: a strong form does not eliminate investigation. It gives the investigator a better starting point.
3. Create Clear Priority Rules
Priority should reflect impact and urgency. It should not depend solely on who reports the problem or who sends the most follow-up messages.
A simple model can combine these two questions:
- How many people or business processes are affected?
- How quickly will the impact become serious?
| Priority |
Typical condition |
Example response |
| Critical |
A major service is unavailable for many people. |
Immediate ownership and frequent updates. |
| High |
A key function is failing, but a limited workaround exists. |
Rapid investigation during the active support period. |
| Medium |
A problem affects some work without blocking essential operations. |
Planned investigation with regular progress updates. |
| Low |
A minor defect, question, or improvement request exists. |
Handle through normal queue planning. |
Write the criteria down and show them to the support team. Consistency matters more than creating a complicated scoring formula.
4. Assign Ownership Immediately
Every open issue needs a visible owner. A team assignment alone may be insufficient because nobody may feel personally responsible for the next action.
Use team ownership for routing, then assign an individual when investigation begins. The assignee should know what action is expected and when the next update is due.
Avoid silent handoffs. When an issue moves between support and engineering, add a short explanation:
- Why the issue is moving.
- What has already been tested.
- What evidence still needs review.
- What the receiving team should do next.
This small habit prevents repeated investigation. It also gives managers a clearer view of blocked work.
5. Use Statuses That Describe Real Progress
A long status list can make a workflow difficult to understand. Use statuses that answer a practical question: what is happening now?
A straightforward flow might include:
- New: the request has arrived and needs review.
- Triaged: the issue has a confirmed category and priority.
- In progress: someone is actively investigating or resolving it.
- Waiting for requester: more information or confirmation is needed.
- Waiting for another team: progress depends on a separate group.
- Resolved: a fix or answer has been provided.
- Closed: the requester has confirmed the outcome, or the closure rule has been met.
Keep “waiting” statuses separate from active work. Otherwise, a report may show a large workload that nobody is currently handling.
6. Build an Escalation Path
Escalation should happen because of defined conditions, not because someone becomes frustrated. Set rules for severity, elapsed time, technical complexity, security risk, and customer impact.
For example, escalate when:
- A critical incident has no owner within ten minutes.
- A high-priority issue has no meaningful progress after two hours.
- The same problem affects several important accounts.
- A possible security or privacy concern appears.
- The support team cannot reproduce or explain the behavior.
The best part? Escalation does not need to feel like blame. It is a routing mechanism that brings the right expertise into the conversation sooner.
7. Keep Requesters Informed
People usually tolerate a delay better when they know what is happening. A short, specific update is more useful than a generic message saying the issue remains under review.
Each update should explain:
- What the team has learned.
- What action is happening next.
- Whether the impact has changed.
- When the next update will arrive.
For example: “We reproduced the error in the latest browser version. Engineering is testing a configuration change, and I will update you by 3 p.m.”
That message sets expectations and shows forward movement, even before the final fix is ready.
8. Confirm the Resolution
Do not close an issue only because someone changed its status. Confirm that the solution addresses the original problem and that the requester understands what changed.
A useful resolution note includes:
- The cause or contributing condition.
- The action taken.
- Any temporary workaround.
- Steps the requester should follow.
- Any follow-up work that remains.
If a permanent fix is still planned, link the related development work and explain the temporary arrangement. This keeps support records honest and useful.
Where Support Teams Lose Time
Most delays come from friction between stages rather than from the technical fix itself. A ticket can sit untouched because nobody knows who owns it, what information is missing, or how serious it is.
Incomplete Requests Create Repeated Questions
Suppose a requester writes, “The application is broken.” A support agent must ask which feature failed, when it happened, who is affected, and whether the problem still occurs.
Several message exchanges may pass before investigation starts. Required fields, examples, and conditional questions reduce this delay.
Ambiguous Ownership Creates Idle Time
A request assigned to “Engineering” may remain untouched because five specialists assume someone else will review it. Assigning a named owner creates a clear next step.
Ownership also makes workload visible. If one person has too many high-priority items, a manager can rebalance work earlier.
Too Many Statuses Hide the Real Queue
Statuses such as “pending review,” “under assessment,” “awaiting analysis,” and “in technical review” may describe nearly identical conditions.
Use fewer statuses with clear definitions. A manager should be able to scan the queue and understand which items are active, blocked, or waiting.
Unclear Escalation Rules Delay Specialist Help
Some teams escalate too early, while others wait until the customer complains repeatedly. Both patterns waste time.
Set measurable triggers. A request that affects a core service should follow a different path from a minor display issue.
Metrics That Show Whether Support Is Improving
Metrics help you identify bottlenecks, but only when each measurement leads to a useful question. A high ticket count alone does not prove poor performance.
First Response Time
First response time measures how long a requester waits before receiving a meaningful reply. An automatic acknowledgment usually should not count as a human response.
This measure helps reveal queue visibility problems. If simple requests wait too long, improve triage coverage or routing rules.
Time to Resolution
Time to resolution measures the period from issue creation to a completed answer or fix. Review this number by priority and request type.
For example, a high average may hide two different problems: quick password requests and slow product defects. Segmenting the results makes the cause easier to see.
Reopen Rate
The reopen rate shows how often an issue returns after closure. A rising rate can indicate incomplete fixes, unclear explanations, or premature closure.
Review reopened requests for patterns. If many customers reopen the same type of issue, improve the resolution checklist or update the related guidance.
Backlog Age
Backlog age shows how long unresolved items remain open. A queue with many old low-priority requests may need a cleanup plan rather than more urgent escalation.
Group old work by reason: waiting for information, waiting for another team, under active investigation, or no longer relevant.
Customer Effort
Customer effort measures how difficult it was to obtain help. You can ask a short question after resolution, such as whether the requester found the process easy.
This metric adds context to speed. A fast answer that forces the requester to repeat the same details may still create a poor experience.
Automation and Knowledge Practices
Automation can remove repetitive handling, while a strong knowledge practice reduces the number of requests that need personal investigation.
Automate Safe, Repetitive Actions
Good automation can assign requests by category, notify an owner, remind someone about an overdue update, or transition an issue after confirmation.
Avoid automating decisions that require judgment. A rule that marks every old issue as resolved may improve a report while damaging trust.
Start with low-risk actions. Measure the result for a few weeks, then expand only when the rule behaves as expected.
Turn Resolutions Into Reusable Guidance
When the same question appears several times, create a clear help article or internal procedure. Explain the symptom, likely cause, steps to try, and escalation conditions.
Use real language from support conversations. If people ask, “Why does my login keep failing after a password change?” use that wording in the guidance.
Review guidance when the product changes. Old instructions can create more tickets than they prevent.
Connect Support With Development
When a support issue becomes a product defect, preserve the investigation history. Include reproduction steps, impact, affected versions, and attempted workarounds.
Development teams can then start with useful context instead of asking support to repeat the entire investigation.
After the fix ships, support should receive a short explanation. This helps agents answer follow-up questions confidently.
Jira Support Solution: ONES.com
Value Proposition
ONES.com combines project management and knowledge management on one platform. ONES Project provides a Jira alternative for teams that need structured issue workflows with fewer disconnected tools.
It supports cloud, on-premise, private cloud, and air-gapped deployments, with the same core feature parity across cloud and self-hosted environments.
Core Capabilities
- Scattered support work → Jira-compatible workflows in ONES Project → teams can organize intake, triage, assignment, and resolution in a familiar issue-based model.
- Limited visibility into progress → Built-in reporting → managers can review workload, aging work, status movement, and team performance in one place.
- Rigid request handling → Custom workflows and fields → support teams can capture details that match their services, approval paths, and escalation rules.
- Manual sprint coordination → Sprint management → development and support teams can plan defect fixes alongside other delivery work.
- Repetitive routing and reminders → Automation → teams can reduce manual transitions, notifications, assignments, and routine follow-up actions.
- Too many separate knowledge tools → ONES Wiki → teams can maintain connected knowledge alongside project and issue work.
- Plugin-heavy configurations → Native platform capabilities → teams can reduce reliance on multiple add-ons for common project and support workflows.
- Restricted deployment requirements → On-premise, private cloud, and air-gapped options → organizations can keep the platform within infrastructure and network boundaries that match their policies.
Application Scenarios
Software product support: A support agent can capture a customer defect, route it to the responsible development team, and track the fix through delivery. The team can preserve technical context without moving between unrelated systems.
Internal service operations: An IT team can separate access requests, incidents, and equipment problems. Each request type can use its own fields, ownership rules, and escalation timing.
Restricted environments: A regulated organization can use a self-hosted or air-gapped deployment when cloud access does not fit its operational requirements. Teams retain structured project and knowledge workflows within the approved environment.
Common Challenges and Practical Solutions
Challenge: The Queue Contains Too Many Vague Requests
Solution: Add request types, required details, and examples. Ask for impact and reproduction steps before the request reaches technical investigation.
Challenge: High-Priority Work Displaces Everything Else
Solution: Reserve capacity for urgent incidents and protect planned work. Review priority criteria regularly so every request does not become an emergency.
Challenge: Support and Engineering Repeat the Same Investigation
Solution: Use a consistent handoff format. Include the symptom, reproduction steps, tests already completed, impact, and expected behavior.
Challenge: Customers Do Not Know What Happens Next
Solution: Set communication rules by priority. Tell requesters when they will receive the next update, even when the technical answer is not ready.
Challenge: Reports Look Good While Customers Remain Frustrated
Solution: Combine operational measures with customer feedback. Review reopen rate, repeated contacts, and effort alongside response and resolution times.
FAQs
What does Jira support usually cover?
Jira support commonly covers issue intake, triage, assignment, investigation, escalation, communication, resolution, and reporting. It may support customer requests, internal service needs, software defects, or access problems. The exact scope depends on your team. A clear service boundary helps people send the right requests to the right queue and prevents Jira from becoming an unstructured general inbox.
How can I reduce Jira ticket resolution time?
Start with better intake information, clear priority rules, immediate ownership, and fewer ambiguous statuses. Separate active work from waiting work, then create escalation triggers for high-impact issues. Review resolution time by request type instead of looking only at one average. This approach helps you find the specific stage causing delays.
Should support teams use separate Jira projects?
Separate projects can make sense when teams need different permissions, workflows, reports, or service boundaries. However, too many projects can make cross-team visibility difficult. Begin with the work structure you actually need. If two teams share ownership, escalation, and reporting requirements, a connected setup may be easier to manage.
What information should a support ticket include?
A useful ticket includes a short summary, detailed symptoms, business impact, affected people, reproduction steps, expected behavior, actual behavior, and relevant environment details. Add recent changes and attempted workarounds when they apply. The right fields depend on the request type. A login problem should not require the same information as a product defect.
When should a Jira issue be escalated?
Escalate when impact is high, progress has stopped, a security concern appears, several important accounts are affected, or specialist knowledge is required. Define timing and severity thresholds before an incident occurs. This removes personal judgment from the first decision and helps support teams involve engineering, security, or management sooner.
Conclusion
Fast Jira support depends on a clear path from request to resolution. Capture useful details, set consistent priorities, assign ownership, communicate progress, and review recurring problems.
But here’s the truth: Jira cannot repair an unclear process by itself. Your team needs practical rules that reduce waiting, repeated questions, and uncertain handoffs.
Start with one improvement this week. Tighten the intake form, simplify statuses, or define escalation triggers. Then measure the effect and build from there. With the right workflow, support becomes easier to follow, easier to manage, and faster for the people who need help.